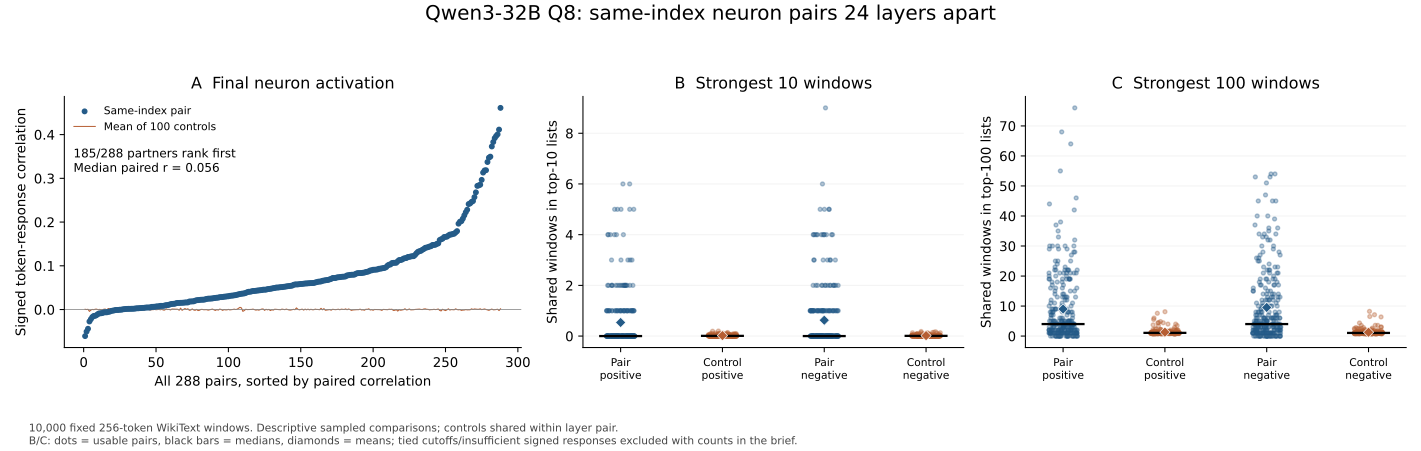
I’m Jeffrey Shorthill, an independent mechanistic interpretability researcher investigating how computational structures and representations develop and change across language models.
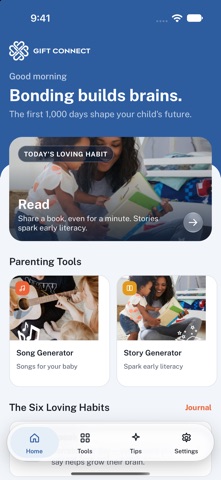
Before moving into full-time research, I helped architect disaster-relief chatbots for Progressive Insurance in 2023 and, over the past two years, worked on AI platforms for underserved families at Gift Connect, a 501(c)(3) nonprofit. That same commitment to using AI to benefit people continues to guide my research.
Questions about AI welfare and moral consideration also motivate my research. I approach them through mechanistic interpretability, studying how the internal organization supporting self-description and experiential language develops and changes.
I use structural analysis, activation measurements, and causal experiments to understand how models organize information, particularly around self-description and situational understanding.
I publish my methods, data, and findings openly to support independent verification, criticism, and collaboration.
Model internalsNeuronal evolutionApplied AIiOS developmentOpen research